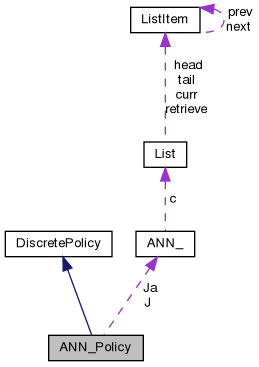
A type of discrete action policy using a neural network for function approximation. More...
#include <ann_policy.h>
Public Member Functions | |
| ANN_Policy (int n_states, int n_actions, int n_hidden=0, real alpha=0.1, real gamma=0.8, real lambda=0.8, bool eligibility=false, bool softmax=false, real randomness=0.1, real init_eval=0.0, bool separate_actions=false) | |
| Make a new policy. | |
| virtual | ~ANN_Policy () |
| virtual int | SelectAction (int s, real r, int forced_a=-1) |
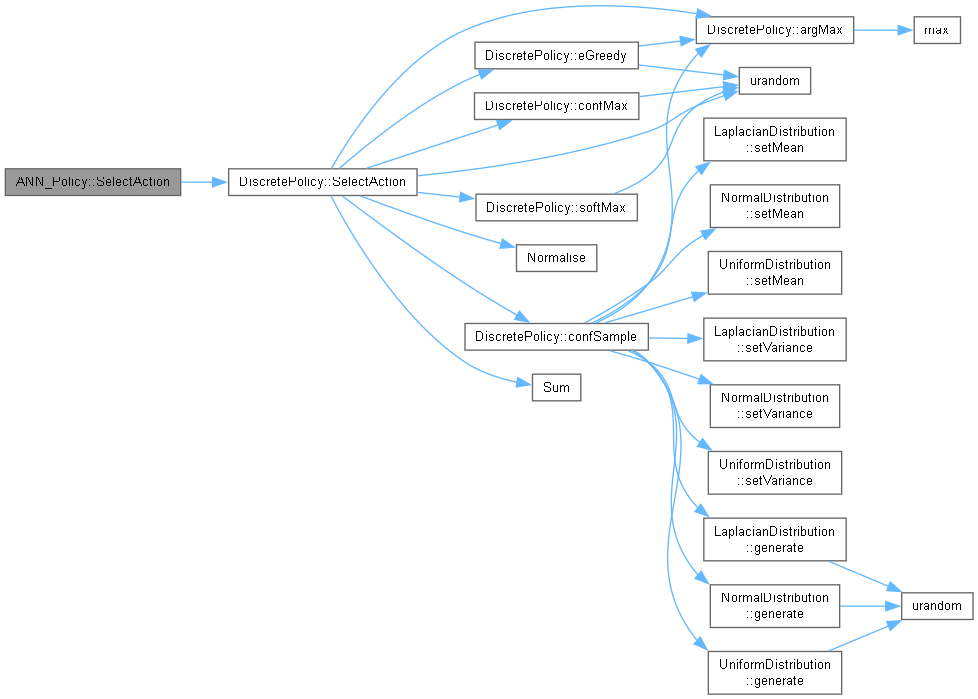
| Keep the base discrete-state overload visible for callers using DiscretePolicy's interface. | |
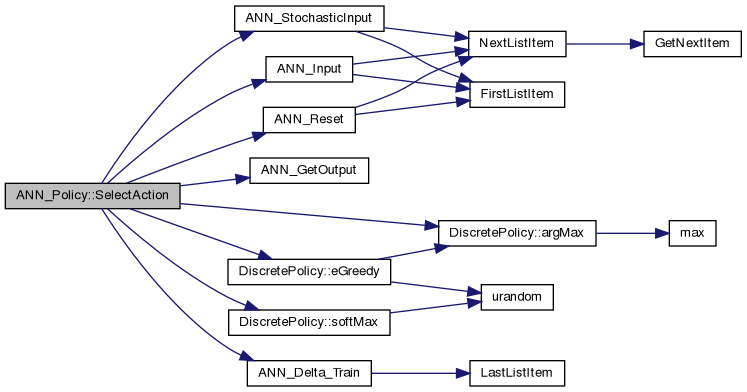
| virtual int | SelectAction (real *s, real r, int forced_a=-1) |
| Select an action, given a vector of real numbers which represents the state. | |
| virtual void | Reset () |
| Reset eligibility traces. | |
| virtual real | getLastActionValue () |
| Return the last action value. | |
| virtual real * | getActionProbabilities () |
| virtual bool | useConfidenceEstimates (bool confidence, real zeta, bool confidence_eligibility) |
| Use confidence estimates with the base class signature. | |
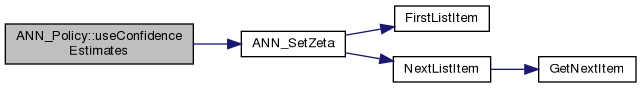
| virtual bool | useConfidenceEstimates (bool confidence, real zeta=0.01) |
| Set to use confidence estimates for action selection, with variance smoothing zeta. | |
| Public Member Functions inherited from DiscretePolicy | |
| DiscretePolicy (int n_states, int n_actions, real alpha=0.1, real gamma=0.8, real lambda=0.8, bool softmax=false, real randomness=0.1, real init_eval=0.0) | |
| Create a new discrete policy. | |
| virtual | ~DiscretePolicy () |
| Kill the agent and free everything. | |
| virtual void | setLearningRate (real alpha) |
| Set the learning rate. | |
| virtual real | getTDError () |
| Get the temporal difference error of the previous action. | |
| virtual void | loadFile (char *f) |
| Load policy from a file. | |
| virtual void | saveFile (char *f) |
| Save policy to a file. | |
| virtual void | setQLearning () |
| Set the algorithm to QLearning mode. | |
| virtual void | setELearning () |
| Set the algorithm to ELearning mode. | |
| virtual void | setSarsa () |
| Set the algorithm to SARSA mode. | |
| virtual void | setForcedLearning (bool forced) |
| Set forced learning (force-feed actions) | |
| virtual void | setRandomness (real epsilon) |
| Set randomness for action selection. Does not affect confidence mode. | |
| virtual void | setGamma (real gamma) |
| Set the gamma of the sum to be maximised. | |
| virtual void | setPursuit (bool pursuit) |
| Use Pursuit for action selection. | |
| virtual void | setReplacingTraces (bool replacing) |
| Use Pursuit for action selection. | |
| virtual void | useSoftmax (bool softmax) |
| Set action selection to softmax. | |
| virtual void | setConfidenceDistribution (enum ConfidenceDistribution cd) |
| Set the distribution for direct action sampling. | |
| virtual void | useGibbsConfidence (bool gibbs) |
| Add Gibbs sampling for confidences. | |
| virtual void | useReliabilityEstimate (bool ri) |
| Use the reliability estimate method for action selection. | |
| virtual void | saveState (FILE *f) |
| Save the current evaluations in text format to a file. | |
Protected Attributes | |
| ANN * | J |
| Evaluation network. | |
| ANN ** | Ja |
Evaluation networks (for separate_actions case) | |
| real * | ps |
| Previous state vector. | |
| real * | JQs |
Placeholder for evaluation vector (separate_actions) | |
| real | J_ps_pa |
| Evaluation of last action. | |
| real * | delta_vector |
| Scratch vector for TD error. | |
| bool | eligibility |
| eligibility option | |
| bool | separate_actions |
| Single/separate evaluation option. | |
| Protected Attributes inherited from DiscretePolicy | |
| enum LearningMethod | learning_method |
| learning method to use; | |
| int | n_states |
| number of states | |
| int | n_actions |
| number of actions | |
| real ** | Q |
| state-action evaluation | |
| real ** | e |
| eligibility trace | |
| real * | eval |
| evaluation of current aciton | |
| real * | sample |
| sampling output | |
| real | pQ |
| previous Q | |
| int | ps |
| previous state | |
| int | pa |
| previous action | |
| real | r |
| reward | |
| real | temp |
| scratch | |
| real | tdError |
| temporal difference error | |
| bool | smax |
| softmax option | |
| bool | pursuit |
| pursuit option | |
| real ** | P |
| pursuit action probabilities | |
| real | gamma |
| Future discount parameter. | |
| real | lambda |
| Eligibility trace decay. | |
| real | alpha |
| learning rate | |
| real | expected_r |
| Expected reward. | |
| real | expected_V |
| Expected state return. | |
| int | n_samples |
| number of samples for above expected r and V | |
| int | min_el_state |
| min state ID to search for eligibility | |
| int | max_el_state |
| max state ID to search for eligibility | |
| bool | replacing_traces |
| Replacing instead of accumulating traces. | |
| bool | forced_learning |
| Force agent to take supplied action. | |
| bool | confidence |
| Confidence estimates option. | |
| bool | confidence_eligibility |
| Apply eligibility traces to confidence. | |
| bool | reliability_estimate |
| reliability estimates option | |
| enum ConfidenceDistribution | confidence_distribution |
| Distribution to use for confidence sampling. | |
| bool | confidence_uses_gibbs |
| Additional gibbs sampling for confidence. | |
| real | zeta |
| Confidence smoothing. | |
| real ** | vQ |
| variance estimate for Q | |
Additional Inherited Members | |
| Protected Member Functions inherited from DiscretePolicy | |
| int | confMax (real *Qs, real *vQs, real p=1.0) |
| Confidence-based Gibbs sampling. | |
| int | confSample (real *Qs, real *vQs) |
| Directly sample from action value distribution. | |
| int | softMax (real *Qs) |
| Softmax Gibbs sampling. | |
| int | eGreedy (real *Qs) |
| e-greedy sampling | |
| int | argMax (real *Qs) |
| Get ID of maximum action. | |
A type of discrete action policy using a neural network for function approximation.
Constructor arguments offer the additional option separate_actions. This is useful for the case of eligibility traces. It allows to use clearing actions traces, since it uses a separate approximator for each action, rather than a single approximator with many outputs.
The class has essentially the same interface as DiscretePolicy. A major difference is the fact that you must supply a real vector that represents the state.
Note that using Q-learning with eligibility traces in this class can result in divergence theoretically.
Definition at line 35 of file ann_policy.h.
| ANN_Policy::ANN_Policy | ( | int | n_states, |
| int | n_actions, | ||
| int | n_hidden = 0, | ||
| real | alpha = 0.1, | ||
| real | gamma = 0.8, | ||
| real | lambda = 0.8, | ||
| bool | eligibility = false, | ||
| bool | softmax = false, | ||
| real | randomness = 0.1, | ||
| real | init_eval = 0.0, | ||
| bool | separate_actions = false ) |
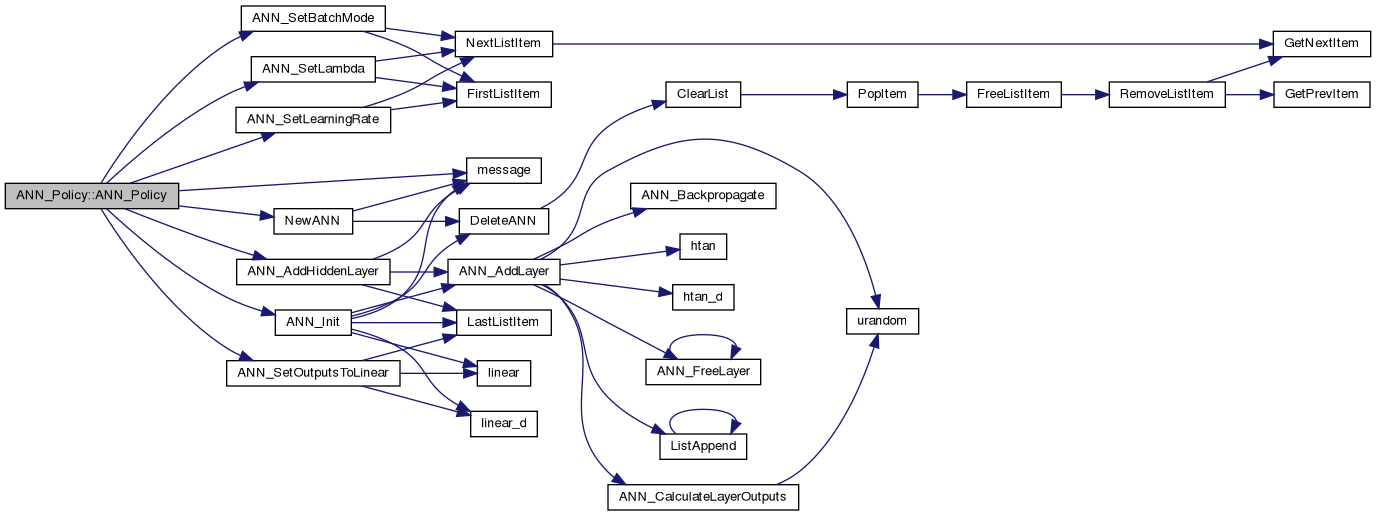
Make a new policy.
Definition at line 17 of file ann_policy.cpp.
|
virtual |
|
inlinevirtual |
Definition at line 60 of file ann_policy.h.
|
inlinevirtual |
Return the last action value.
Reimplemented from DiscretePolicy.
Definition at line 58 of file ann_policy.h.
|
virtual |
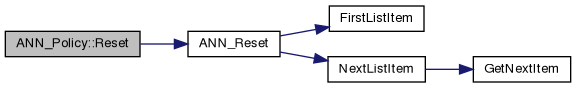
Reset eligibility traces.
Reimplemented from DiscretePolicy.
Definition at line 180 of file ann_policy.cpp.
|
virtual |
Keep the base discrete-state overload visible for callers using DiscretePolicy's interface.
Reimplemented from DiscretePolicy.
Definition at line 75 of file ann_policy.cpp.
Select an action, given a vector of real numbers which represents the state.
Definition at line 80 of file ann_policy.cpp.
|
virtual |
Use confidence estimates with the base class signature.
Reimplemented from DiscretePolicy.
Definition at line 191 of file ann_policy.cpp.
|
virtual |
Set to use confidence estimates for action selection, with variance smoothing zeta.
Definition at line 198 of file ann_policy.cpp.
|
protected |
Scratch vector for TD error.
Definition at line 43 of file ann_policy.h.
|
protected |
eligibility option
Definition at line 44 of file ann_policy.h.
|
protected |
Evaluation network.
Definition at line 38 of file ann_policy.h.
|
protected |
Evaluation of last action.
Definition at line 42 of file ann_policy.h.
|
protected |
Evaluation networks (for separate_actions case)
Definition at line 39 of file ann_policy.h.
|
protected |
Placeholder for evaluation vector (separate_actions)
Definition at line 41 of file ann_policy.h.
|
protected |
Previous state vector.
Definition at line 40 of file ann_policy.h.
|
protected |
Single/separate evaluation option.
Definition at line 45 of file ann_policy.h.
 1.14.0

